Used together, they’re one of the single biggest levers for cutting both query time and cost on large datasets.
Query engines that scan data in cloud storage — Amazon Athena, Spark, BigQuery these largely charge based on how much data they have to read, not how much data actually matches your query. A poorly laid-out dataset forces the engine to scan everything just to find a handful of relevant rows.
Partitioning and bucketing are the two primary techniques for avoiding that waste. Get the layout right, and a query that would have scanned terabytes might only touch a few megabytes. Get it wrong or skip it entirely and every query on a growing dataset gets slower and more expensive over time, often without anyone realizing why until the monthly cloud bill shows up.
If you’re a tech lead / an architect working with large datasets in S3, a data lake, or a warehouse, this is one of the highest leverage, lowest-effort optimizations available and one of the most commonly skipped by teams still new to the space.
Partitioning physically splits a dataset into separate folders or the warehouse equivalent based on the value of one or more columns — most commonly a date.
A partitioned layout in S3 looks like this:
s3://my-bucket/orders/
  year=2026/month=09/day=24/  <- one file (or more) here
  year=2026/month=09/day=25/
  year=2026/month=09/day=26/
When a query filters WHERE year=2026 AND month=9 AND day=26, the engine only reads the one matching folder and this is called partition pruning, and it’s the entire reason partitioning exists.
Choosing a partition key — the core tradeoff:
AWS Athena Example (ref)
(column_name data_type) clause.CREATE EXTERNAL TABLE [IF NOT EXISTS]
[db_name.]table_name [(col_name data_type [COMMENT col_comment] [, ...] )]
[COMMENT table_comment]
[PARTITIONED BY (col_name data_type [COMMENT col_comment], ...)]
[CLUSTERED BY (col_name, col_name, ...) INTO num_buckets BUCKETS]
[ROW FORMAT row_format]
[STORED AS file_format]
[WITH SERDEPROPERTIES (...)]
[LOCATION 's3://amzn-s3-demo-bucket/[folder]/']
[TBLPROPERTIES ( ['has_encrypted_data'='true | false',] ['encryption_option'='SSE_S3 | SSE_KMS | CSE_KMS',] ['kms_key'='aws_kms_key_arn',] ['classification'='aws_glue_classification',] property_name=property_value [, ...] ) ]-- Partitioned AND bucketed table, using Athena's documented CLUSTERED BY syntax
CREATE EXTERNAL TABLE orders (
order_date STRING,
order_id STRING,
customer_id STRING,
amount DOUBLE
)
PARTITIONED BY (order_date STRING)
STORED AS PARQUET
LOCATION 's3://my-bucket/orders/'
TBLPROPERTIES (
'bucketing_format' = 'spark'
);AWS Athena Example
-- Partitioned AND bucketed table, using Athena's documented CLUSTERED BY syntax
CREATE EXTERNAL TABLE orders (
    order_date     STRING,
    order_id       STRING,
    customer_id    STRING,
    amount         DOUBLE
)
PARTITIONED BY (order_date STRING)
CLUSTERED BY (customer_id) INTO 8 BUCKETS
STORED AS PARQUET
LOCATION 's3://my-bucket/orders/'
TBLPROPERTIES (
  'bucketing_format' = 'spark'
);
A query that benefits from both
SELECT SUM(amount)
FROM orders
WHERE order_date BETWEEN '2026-09-20' AND '2026-09-26'
  AND customer_id = '12345';
-- If this table is partitioned by order_date and bucketed by customer_id,
-- Athena calculates the exact bucket for this prders and reads
-- at most one file per matching partition — not the whole partition.CREATE TABLE orders_optimized
WITH (
format = 'PARQUET',
external_location = 's3://my-bucket/orders_optimized/',
partitioned_by = ARRAY['order_date'],
bucketed_by = ARRAY['customer_id'],
bucket_count = 8
) AS
SELECT order_id, customer_id, amount, order_date
FROM orders_raw;CREATE TABLE orders_copy AS SELECT * FROM orders_rawPartitioning and bucketing decisions are made at the storage stage, but they’re really a bet on how the data will be queried later and which is why they connect directly to Data Architecture decisions as much as engineering ones:
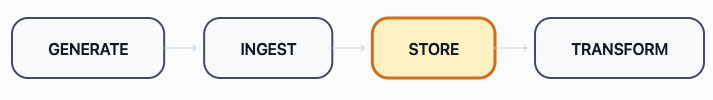
The practical rule before choosing a partition key, ask how the table will actually be queried and not what feels like the “natural” way to organize the data.
| Company / Scenario | Partitioning / bucketing strategy | Why |
|---|---|---|
| Swiggy/Zomato — analyzing order history | Partition by order_date, bucket by restaurant_id | Most analytics queries filter by a date range and often a specific restaurant — this layout lets both filters narrow the scan dramatically. |
| A bank — transaction history for compliance queries | Partition by transaction_date, bucket by account_id | Regulatory and fraud-investigation queries typically ask “show me this account’s activity in this date range” — exactly the two-dimensional filter this layout is built for. |